Text & writing
Exact vs. Near-Duplicate Lines: Why Matches Fail
To a computer, two lines are duplicates only if they contain exactly the same characters. Many lines that look identical to a person are not identical at all. This guide explains the invisible differences that stop duplicates from matching and how to deal with each one.
Ready to try the tool this guide describes?
Differences you can see
- Capitalization: “Apple” and “apple”.
- Spacing inside the line: “New York” and “New York” (two spaces).
- Punctuation variants: a straight apostrophe (') versus a curly one (’), or a hyphen versus a dash.
Differences you cannot see
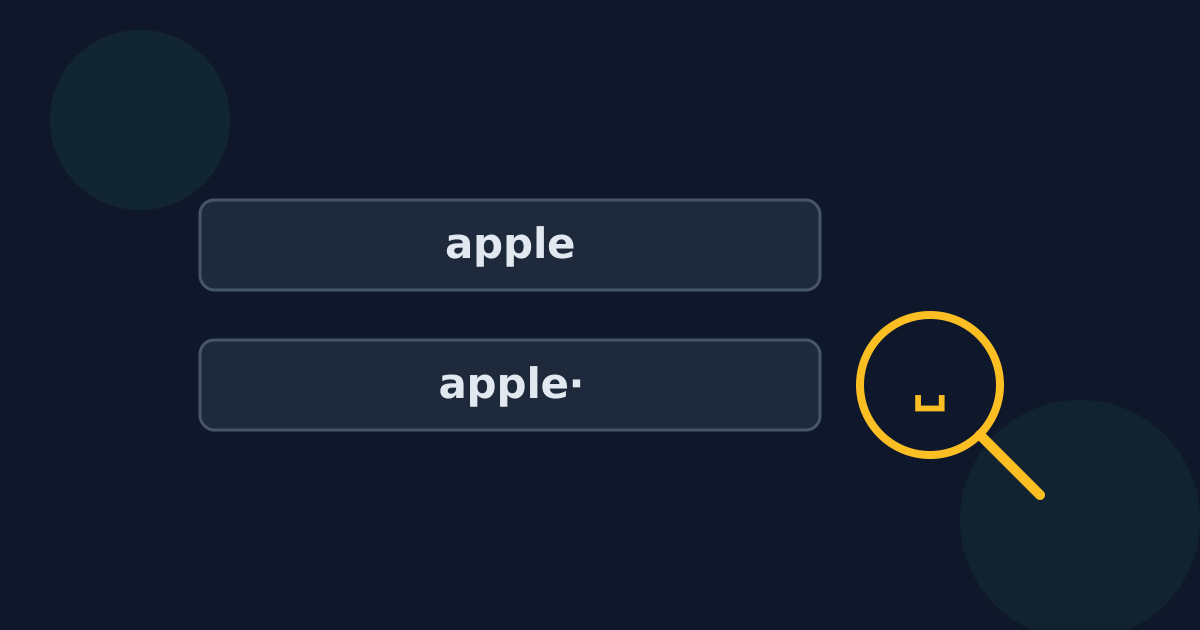
- Trailing spaces or tabs at the end of a line.
- Non-breaking spaces, which look like ordinary spaces but are a different character.
- Zero-width characters, which take up no space at all.
- Different Unicode forms of the same letter: “é” can be stored as one character or as “e” plus a combining accent, and both look the same.
Unicode normalization
Unicode defines normalization forms so that equivalent text can be compared reliably. NFC combines letters and accents into single characters where possible; NFD splits them apart. Programming languages provide this — in JavaScript, for example, text.normalize("NFC") — so data can be normalized before it is compared.
Getting near-duplicates to match
- Remove extra spaces first so spacing differences disappear.
- Turn on case-insensitive matching if capitalization should not matter.
- Ignore spaces at the start and end of lines if trailing spaces are the problem.
- For data work, normalize Unicode and standardize punctuation before comparing.
Exact vs. Near-Duplicate Lines FAQ
- Why are identical-looking lines not treated as duplicates?
- They differ by a character you cannot see, such as a trailing space, a non-breaking space, or a different form of an accented letter.
- What is Unicode normalization?
- A standard way of converting equivalent text to one consistent form, such as NFC or NFD, so that it compares as equal.
- How do I remove duplicates regardless of case?
- Use a case-insensitive option, which compares lines as if they were all lowercase while keeping the original text of the first copy.
- Can trailing spaces create duplicates?
- They prevent matches: “apple” and “apple ” are different lines unless the comparison ignores edge spaces.
- Are straight and curly apostrophes the same character?
- No. They are different characters, so lines that differ only by apostrophe style do not match exactly.
Related guides
- Why Duplicate Lines AppearHow merged lists, repeated exports, logs, and double submissions create duplicate lines — and when a repeated line is meaningful and should stay.
- Duplicate Rows vs. LinesThe difference between removing duplicate lines from text and duplicate rows from a spreadsheet, why CSV files need care, and which approach to use.
Open the tool
Jump into Remove Duplicate Lines when you are ready to process your files.